What I learned while building a reliable in-app notification pipeline
When I first thought about adding notifications to ModusFocus, the requirement appeared simple: place a bell icon in the header and show users when something important happens.
It only came out that creating bell icon was most simplest part. The real work was deciding how notifications should be created, delivered, stored, retrieved, marked as read, and observed—without slowing down the main task-management workflows or introducing unnecessary infrastructure too early.
The initial problem
For ModusFocus, we wanted an in-application notification centre that informs users about events such as:
- A task being assigned.
- A task being completed or cancelled.
- Project membership changes.
- Workspace membership and role changes.
The notification system therefore had to meet a few important requirements:
- It must not slow down the main business operation.
- Each notification must belong to a specific set of recipient.
- The UI must be able to retrieve new notifications efficiently.
- Users must be able to mark one or all notifications as read.
- Duplicate processing must not create duplicate notifications.
- Failures must be traceable across services.
- The first version must remain simple enough to operate as an MVP.
Considering and weighing options in depth
WebSockets and SSE in a distributed deployment
Both WebSockets and Server-Sent Events create long-lived connections between the browser and a specific application pod.
Consider a deployment with three pods:
Browser ──persistent connection──> Pod A

Task update request ──────────────> Pod B
Notification created ─────────────> Pod C
Pod A owns the browser connection, but the event may be produced or processed by Pod B or Pod C. An in-memory notification published inside Pod C is not automatically visible to Pod A.
To deliver the event to the correct browser, the pods need a shared event-distribution mechanism:
Task or membership event
        ↓
Notification created
        ↓
Redis Pub/Sub, Kafka or another message broker
        ↓
Every connected notification pod receives the event
        ↓
The pod owning the user’s connection sends it to the browser
This mechanism applies to both approaches:
- With WebSockets, the owning pod sends the event through the user’s socket.
- With SSE, the owning pod writes the event to the user’s open HTTP stream.
Why sticky sessions are not sufficient
A load balancer can use sticky sessions so that a browser reconnects to the same pod. However, this only helps maintain connection affinity.
It does not solve the main distribution problem: a notification can still be created by another pod or service. The connection-owning pod must still learn about that event through Redis Pub/Sub, a message broker, or a comparable shared backplane.
A production implementation would consequently require:
- Reconnection and missed-event handling.
- Cross-pod event distribution.
- Broker subscription management.
- Duplicate-event handling.
- Pod shutdown and connection-draining behaviour.
- Monitoring for both the persistent connections and the shared event backplane.
This was more infrastructure than the initial ModusFocus notification centre required.
How polling simplifies this
Polling keeps the frontend and task API stateless:
Browser
   ↓ periodic GET
Any task-api pod
   ↓
Shared notification store
The browser can send each polling request to any available pod. That pod reads the current unread state from the shared notification database:
GET /notifications?status=UNREAD&limit=20There is no need to know which pod created the notification or which pod handled the previous request. The database is the durable shared source of truth.
Polling still requires deduplication, lifecycle management, and stale-response protection in the frontend, but it avoids the persistent-connection and cross-pod event-distribution layer.
System Design
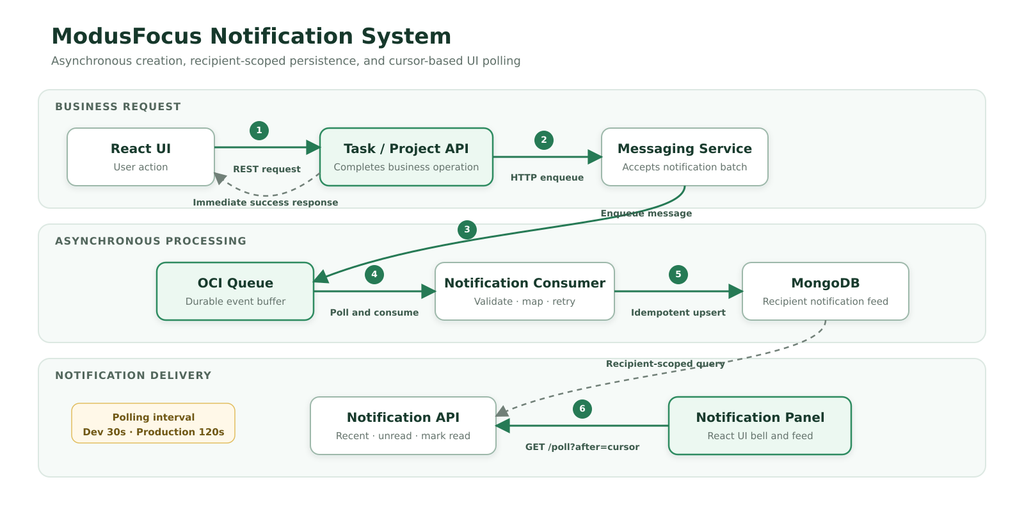
The ModusFocus notification system uses two complementary delivery models. Notification creation is asynchronous, while notification retrieval is polling-based.
For example, when User A assigns a task to User B, the Task API first validates permissions and completes the assignment. Only after the business operation succeeds is a notification sent to the queue. A background consumer processes it and stores the recipient-specific notification in MongoDB.
This keeps notification processing loosely coupled from the main business operation. Queue delays or notification-processing failures do not block a successful task assignment. The UI then periodically polls the Notification API to retrieve the latest unread notifications.
Centralizing notification scenarios
One concern I had was that every service could eventually start building notification messages in its own way. That would scatter templates and rules across the codebase and make even a small wording change difficult.
To avoid that, I created a central notification scenario catalogue in code. It includes events such as TASK_ASSIGNED, TASK_COMPLETED, PROJECT_MEMBER_ADDED, and WORKSPACE_MEMBER_ROLE_CHANGED.
For every scenario, the catalogue defines:
- The notification type.
- The related entity type.
- The message template.
I deliberately kept the code as the single source of truth instead of duplicating the same configuration in YAML.
The business services still provide the facts about what happened and who was affected. The shared dispatcher handles recipient resolution, prevents self-notifications, renders the message, and sends it for asynchronous processing.
This gave me one clear place to understand and update notification messages while keeping the underlying business rules close to the services that own them.
Observability across the queue
Asynchronous processing creates a gap between the request that triggers an event and the consumer that stores the notification. Without correlation, troubleshooting that path becomes difficult.
The producer therefore propagates tracing context with the notification message. The consumer continues the trace and records spans for validation and MongoDB persistence.
This makes it possible to determine whether:
- The original business action succeeded.
- The notification message was produced and queued.
- The consumer received it.
- Persistence succeeded or failed.
- End-to-end delivery became unusually slow.
Useful metrics include messages produced, messages consumed, failures, duplicates ignored, queue age, and notification delivery latency.
Lesson Learned
- A notification is a business event, not merely a UI message. Recipient selection, authorization, idempotency, and lifecycle belong in the backend design.
- Keep secondary work outside the critical transaction. A notification failure should not invalidate an otherwise successful task or membership operation.
- Centralize scenarios and recipient rules. This prevents inconsistent templates and scattered business logic.
- Carry observability across asynchronous boundaries. Tracing only the producer leaves the most important part of the delivery path invisible.
- Choose infrastructure based on current product needs. Polling is less exciting than WebSockets, but it is the right trade-off for this stage of ModusFocus.
Closing Notes
The resulting system is intentionally practical: domain services create meaningful notification events, the messaging service and queue decouple delivery, a consumer stores recipient-specific notifications in MongoDB, and the UI retrieves them through configurable polling.
It is not designed to predict every future notification feature. Instead, it creates clear boundaries that solve today’s problem while allowing the system to evolve when ModusFocus genuinely needs real-time delivery, more recipients, or additional channels.